The Claude outage
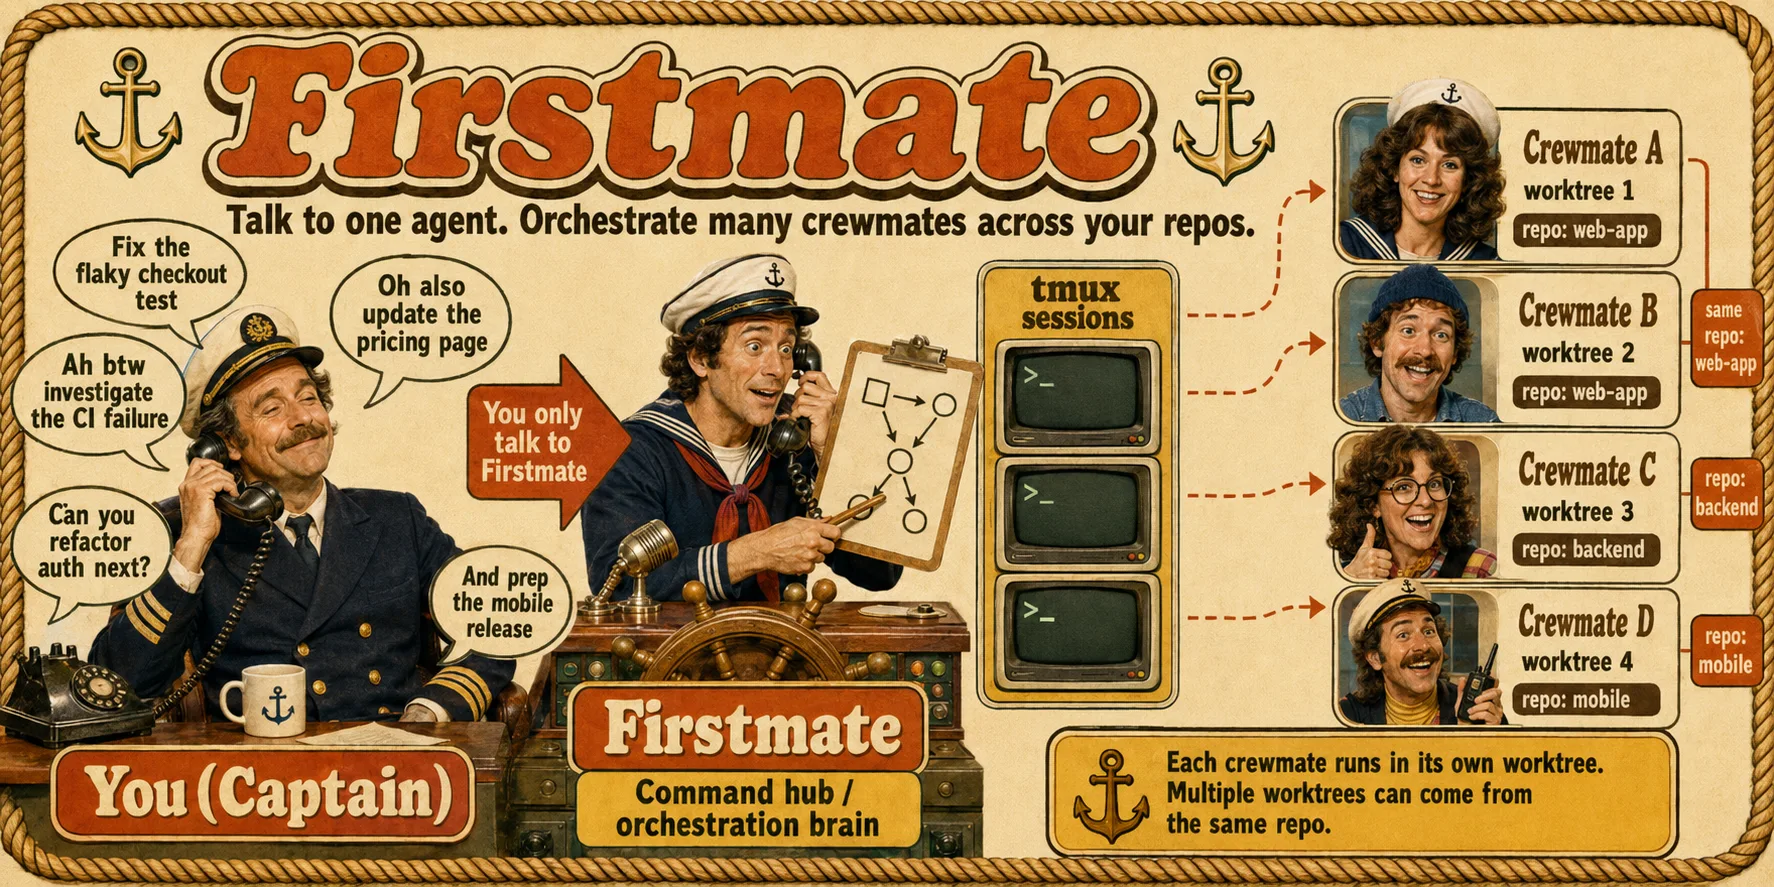
I get tired, I have weekends, I go out. AI does not. I started this week watching Kun Chen’s video on building a full-stack app with agentic engineering, where he shows his tool, firstmate: one agent in front, a whole crew behind it, every task in its own disposable worktree, finished pull requests handed back, and how he is currently doing his software development.
At first I didn’t realize how much I had learned — until Thursday night.
Claude Outage. It went down for hours. All my development process stopped — I wasn’t the only one.
Say it out loud and it stops sounding small: I am the one person responsible for all of my own AI infrastructure — and I had built Claude into a single point of failure for my own ability to work. I run the infrastructure so that outages route around me, not through me. There was no reason my work should die with one subscription. It’s time to refactor and upgrade!
The crew, diagrammed
Silverdragon now hosts one crew. They are the ones responsible for doing asynchronous development that I can leave alive for 6+ hours (my sleep routine). Development runs mainly on tier 0, and the /gsd planning runs on Claude — the Fable Max (5x) plan is better at it.
In progress!
Hey — this is a live website! It takes time for me to build and correctly adopt everything to communicate with everyone. :D